Site Reliability Engineering (SRE) Consulting
Reliability is a product feature. I help teams measure it, protect it and automate away the work that gets in the way, drawing on years as a Principal SRE running planet-scale on-premise and cloud environments.
What I help with
- Define and track SLOs, with the observability needed to make them trustworthy
- Incident management and post-mortem culture that improves systems instead of assigning blame
- On-call design that prevents burnout
- Capacity planning and usage forecasting for infrastructure growth
- Automation that removes SRE toil: upgrades, migrations and provisioning
- Chaos and resilience testing practices for production systems
Relevant experience
- Principal SRE (Consultant) at Virtasant since Feb 2024: planet-scale environments on-premise and on AWS
- Kept five 9's of availability through a full AWS ECS to EKS migration at Twilio Segment
- Improved the observability landscape for better SLO tracking of services
- Built an infrastructure usage-forecasting backend and growth dashboards
- Mentored engineers through their SRE and DevOps journey; interviewed SRE candidates worldwide
Related articles
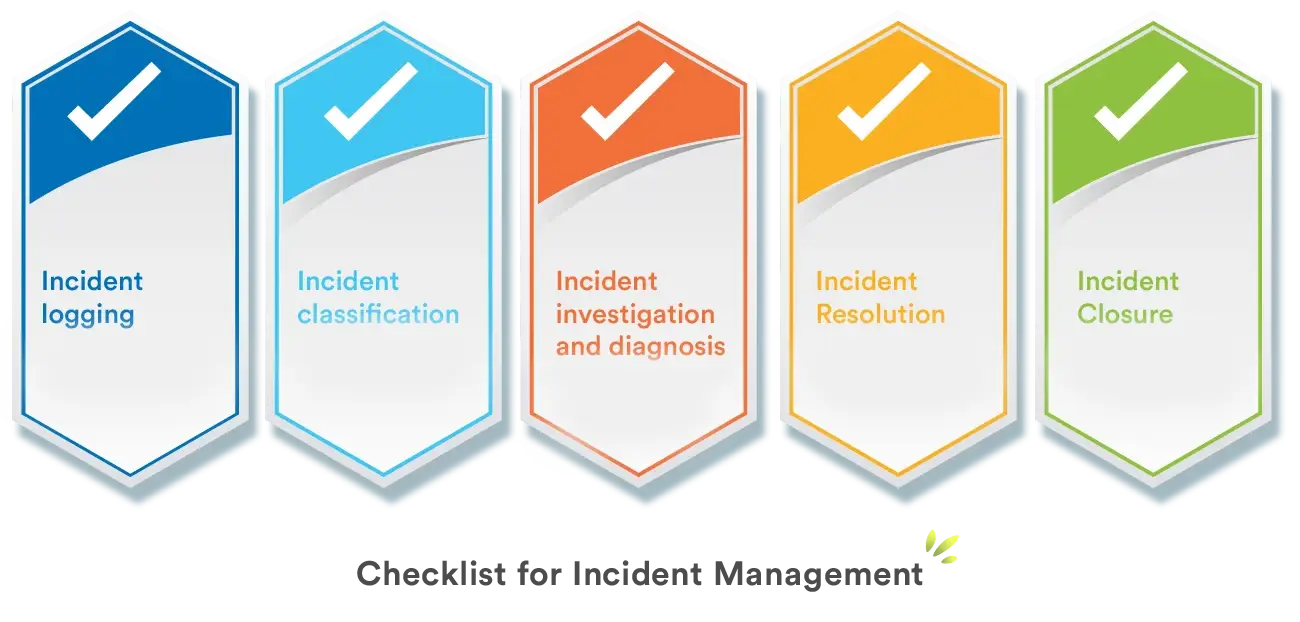
Incident Management: Post-Mortem Culture That Works
The world of complex distributed systems is inherently unpredictable. Despite our best efforts in design, testing, and deployment, incidents are not a question of “if,” but “when.” For Site Reliability Engineers, Softwar
On-Call Best Practices: Preventing Burnout
The relentless hum of production systems, the constant vigilance required to maintain their health, and the inevitable late-night pages are an inherent part of the modern software engineering landscape. For Site Reliabil
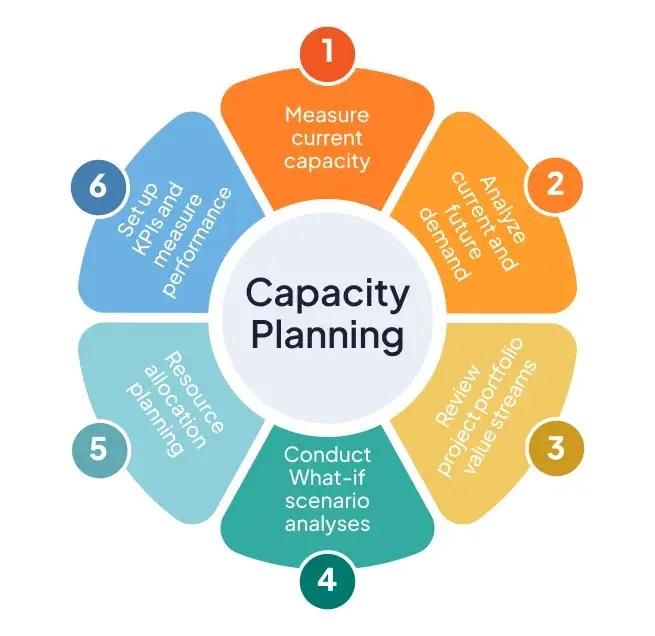
Capacity Planning in the Cloud Era
In the dynamic landscape of cloud computing, managing infrastructure effectively is less about static provisioning and more about intelligent, adaptive resource orchestration. Capacity planning, once a periodic, often te
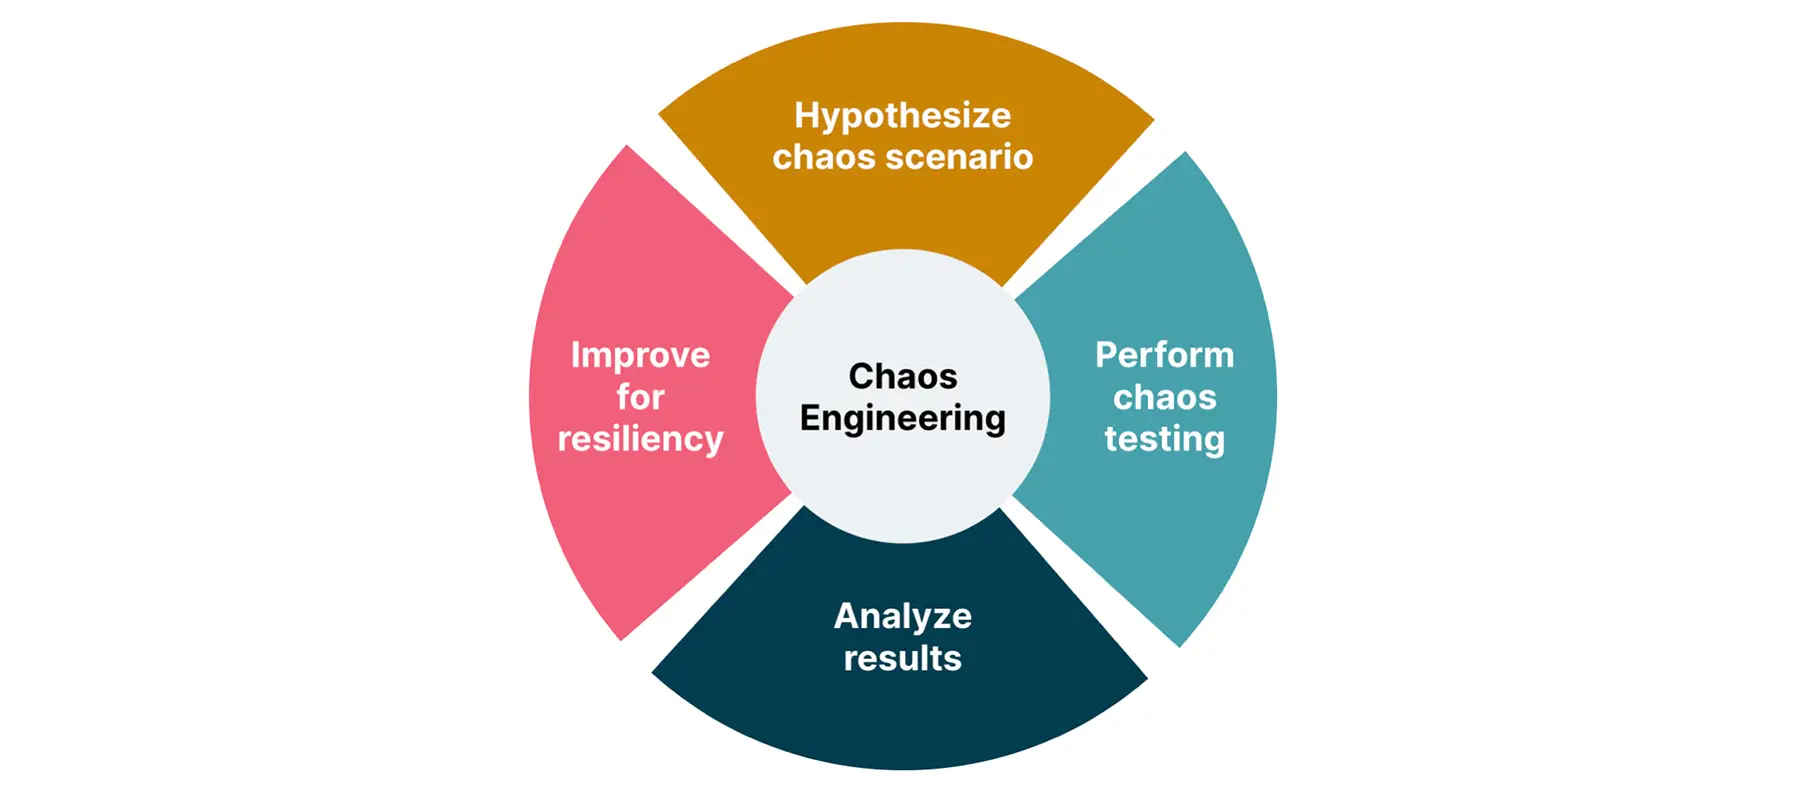
Chaos Engineering in Production: A Practical Guide
We’ve all been there. It’s 3 AM, and the pagers are screaming. A critical service is down, customers are impacted, and the on-call team is scrambling through logs and dashboards, trying to piece together a puzzle in the